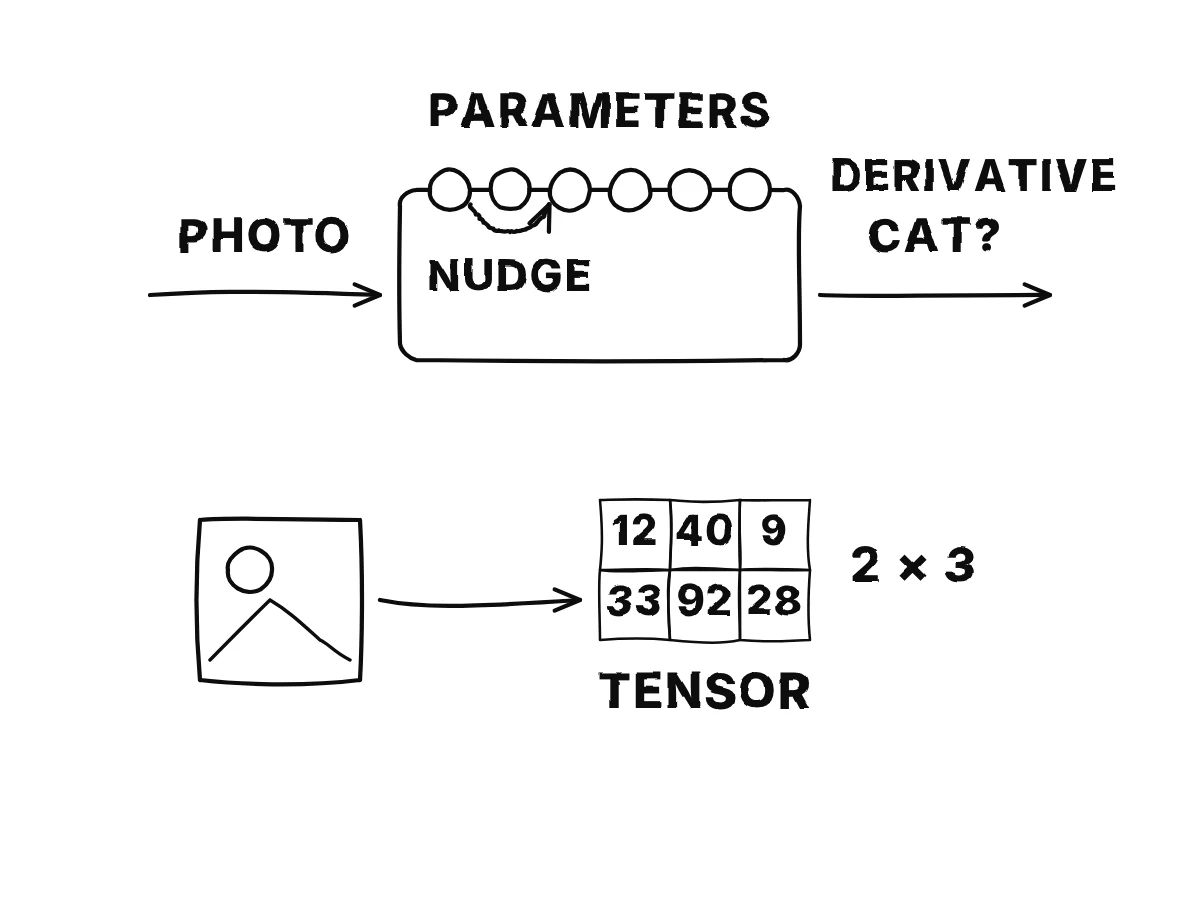
One Simple Recipe, Scaled Up
Learning Is a Search
Looking under the hood starts with one idea: learning is a search. You write a program with a vast number of adjustable knobs, called parameters, and you turn them until the program behaves well.
Alice's Adventures in a Differentiable Wonderland, Volume I: A Tour of the Land
The same text, told at every level, in every language and look shown here. Pick, then listen or download.
The same player the product gives for your own book: the voice, the drawings as they are drawn, the text.
A modern textbook on how neural networks really work, from tensors and gradients to transformers. The first three chapters lay the ground: what the book is about, the linear algebra and calculus a network runs on, gradient descent, and what a dataset and a loss function are.
This is a sample: 3 of 13 chapters.
Looking under the hood starts with one idea: learning is a search. You write a program with a vast number of adjustable knobs, called parameters, and you turn them until the program behaves well.
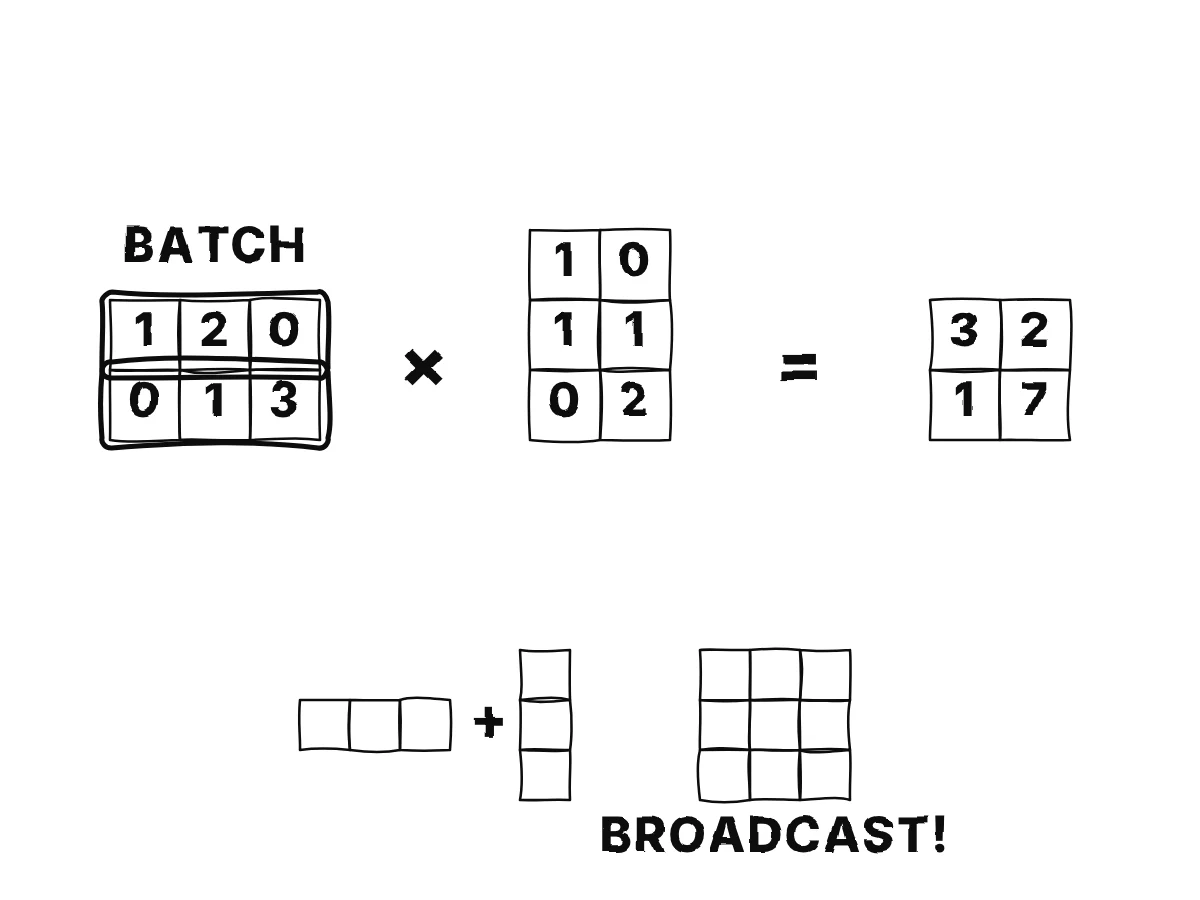
A table of numbers, a matrix, can be read as a stack of such vectors, one per row, and the book calls this a batch of data. Multiplying matrices is then nothing more than computing many dot products at once, every row of one against every column of the other, in a single operation.
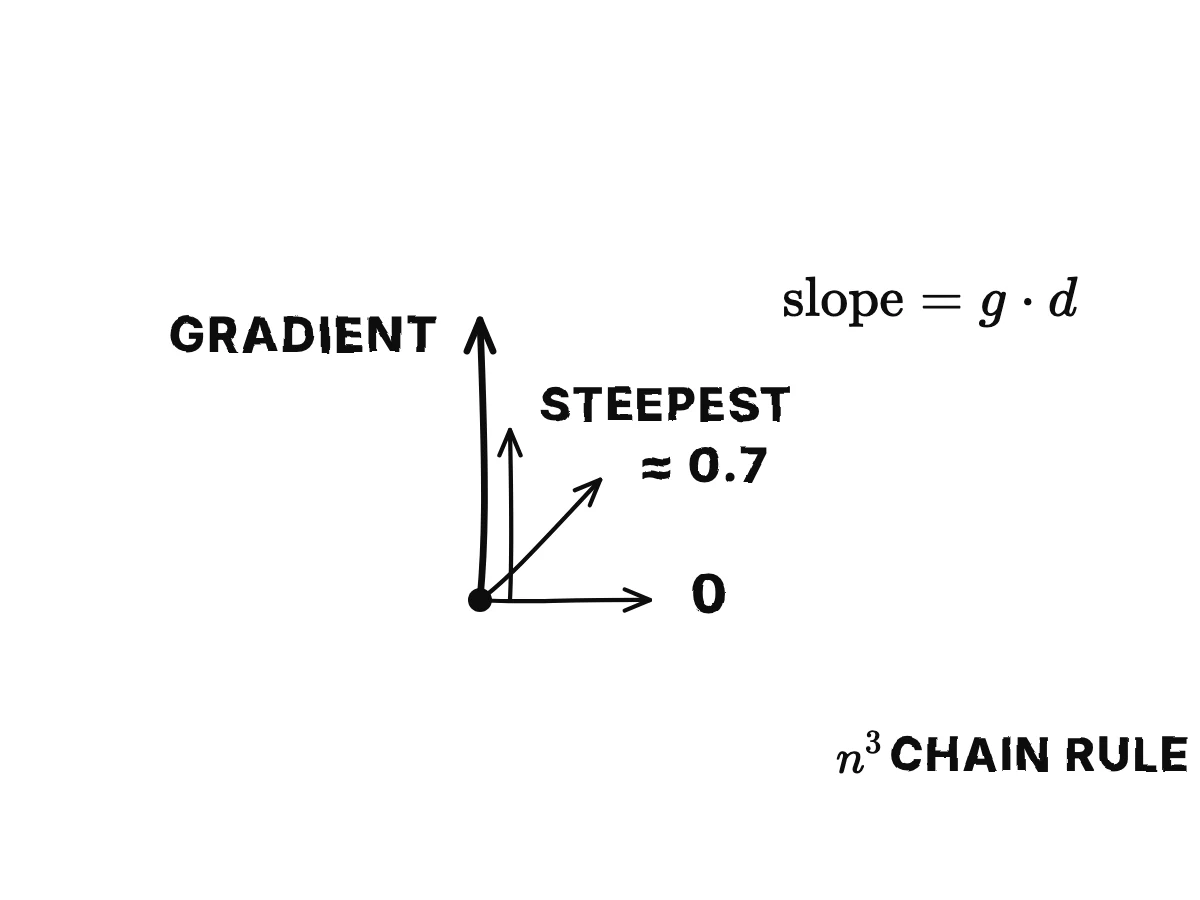
Stand on a sloping lawn or a ramp and take one small step in several directions: straight up, sideways, diagonally. You should feel the steepest climb in one direction, no climb at all at right angles to it, and partial climbs in between.
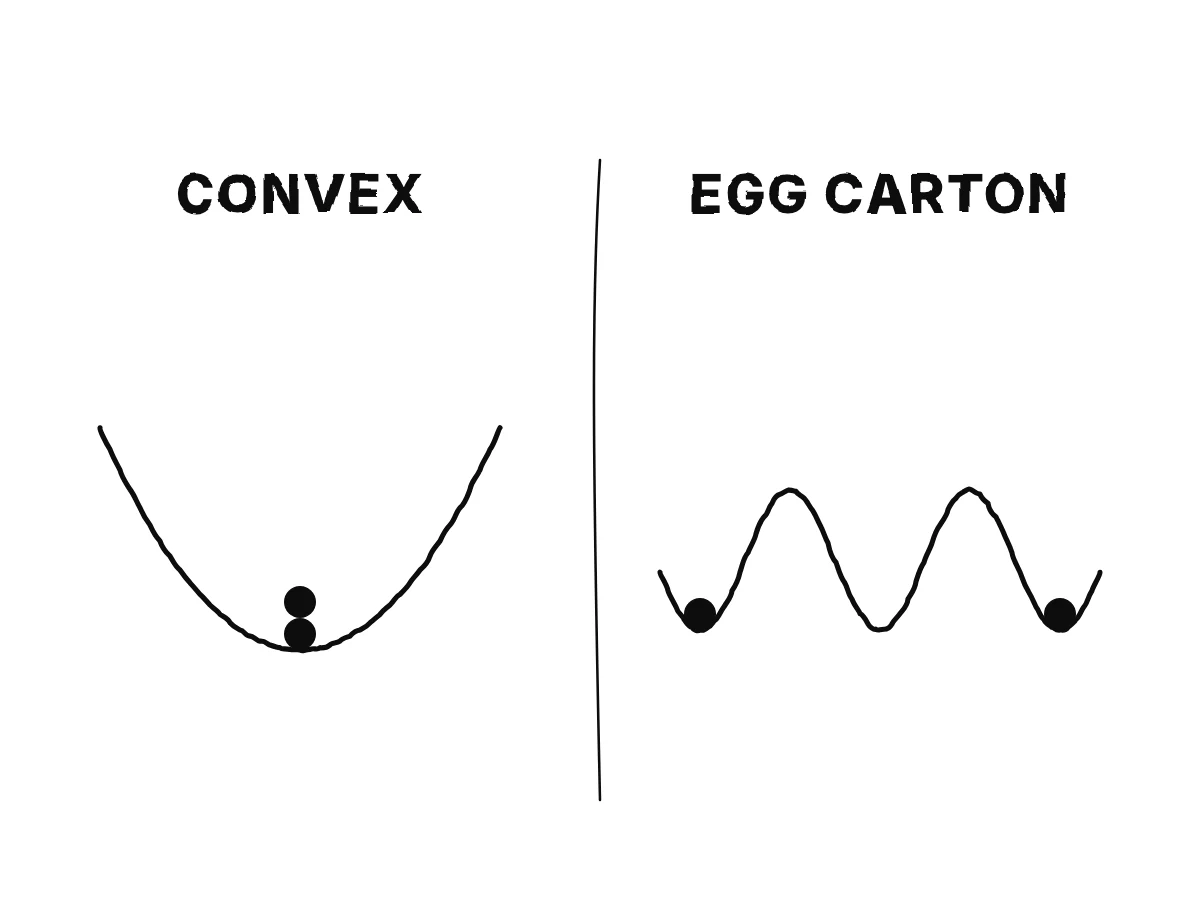
Where does the walk end? It stops where the ground is flat, a stationary point, but flat ground can be a valley floor, a hilltop, or a saddle like a mountain pass that falls one way and rises the other.
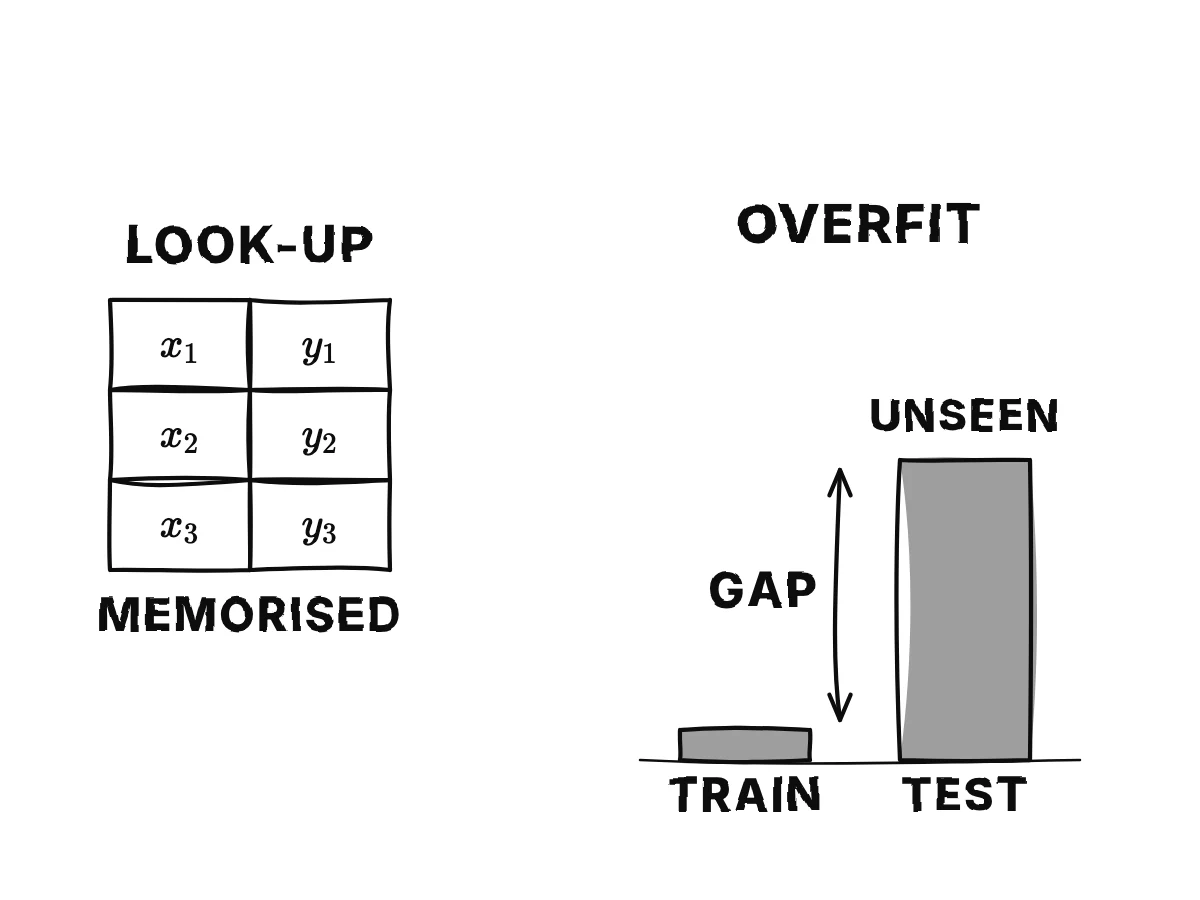
Then comes a trap. The average loss on the training examples can always be made perfect by a cheat: a look-up table that stores every example and answers with it, and gives some default for anything else. That table has memorised and learned nothing, exactly like your friend with last year's test.
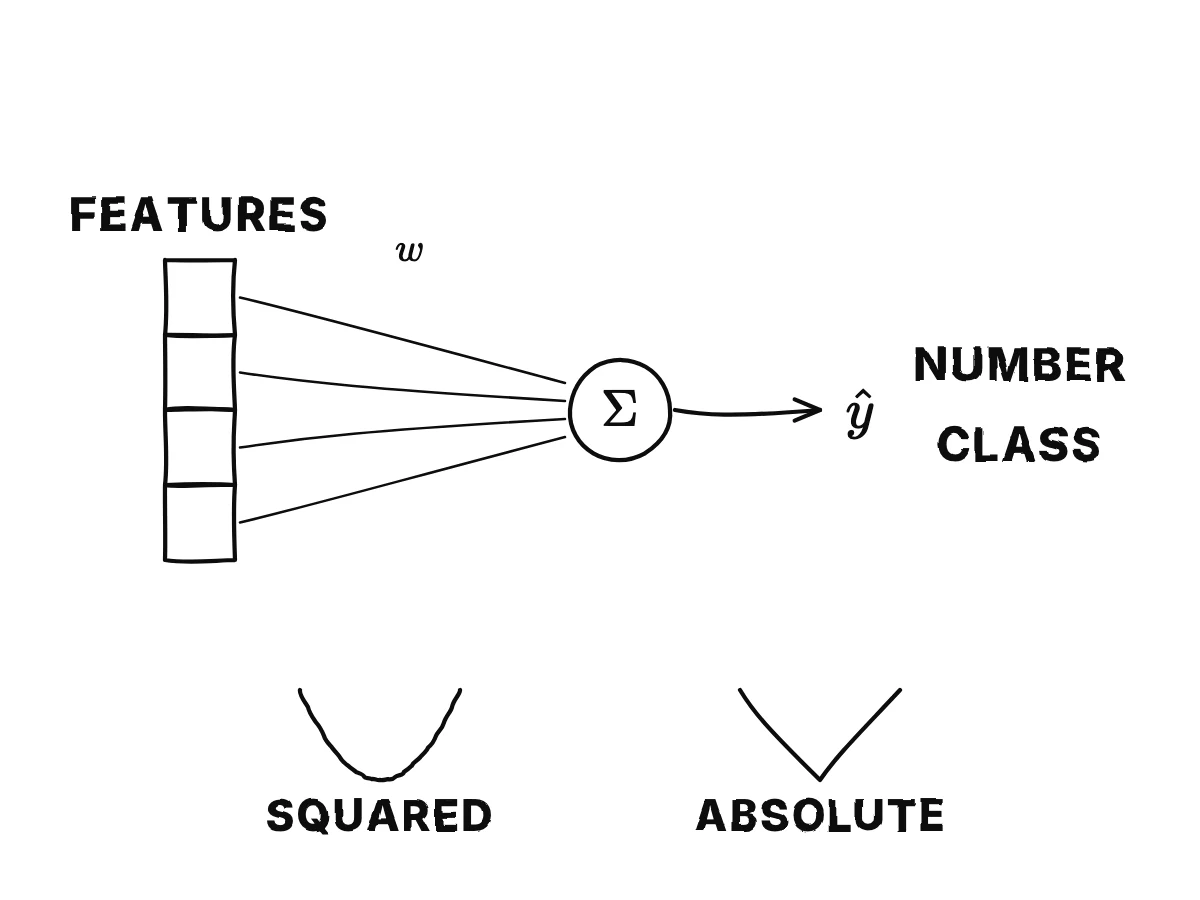
Chapter 4 now builds the simplest block of all, the linear model, of which the book says every differentiable model is a clever variation.
Examples for: a curious adult with school maths who uses AI apps every day; add one modern instance per idea, such as how a chat assistant or a phone's photo app is trained
The lectures retell the English text of arXiv 2404.17625 (version 3, 2025) by Simone Scardapane, published under an open licence that allows retelling and translation. The retelling, the drawings and the voice are made by AI and checked against the book by a second model. How AI is used.
The lectures adapt the original and are released under the same licence, free to share and adapt with credit to the author and a link to this page: CC BY-SA 4.0
Upload a textbook or any difficult book. The first five minutes are free.
Upload a book